ChargePoint Engineering Manager Narasimha Reddy Annapareddy on the Record That Has to Survive the Trip
Most software failures announce themselves. A page throws an error, a service times out, a test goes red. Integration failures are different. When a record moves from one system to another and arrives with a field missing, a currency rounded the wrong way or a status that the receiving system does not recognise, nothing breaks. The data simply becomes slightly less true, and it stays that way until someone in finance tries to close the month and the numbers refuse to agree.
Narasimha Reddy Annapareddy, who leads NetSuite Business Systems at ChargePoint, judged a batch of fourteen projects at DOGFOOD 2026, a 72-hour hackathon in which every team built the same product: a platform for running hackathons. He read them the way an integration engineer reads any system, by following the records.
A Career Spent Between Systems
Annapareddy has spent more than fourteen years building enterprise software, most of it in the space where one system hands data to another. At ChargePoint he is Manager of NetSuite Business Systems, a role he moved into after joining the company as a Staff NetSuite Engineer nearly three years ago. Before that he worked at Quotient Technology, Microbiologics and Tata Consultancy Services.
His work connects NetSuite to the rest of a company’s operations: Salesforce, Stripe, Workday, Concur and SPS Commerce EDI, built through MuleSoft, Dell Boomi and Celigo connectors. He has delivered full lifecycle NetSuite implementations and web store builds on SuiteCommerce Advanced, works across SuiteScript, SuiteTalk, SuiteFlow and the SuiteCloud Development Framework, and has delivered against Snowflake, BigQuery, Superset and Anaplan in retail, healthcare, manufacturing, and food and agriculture. He holds an MS in Computer Science from the University of Central Missouri, is an IEEE Senior Member and a member of the IET, and has development experience across C, C++, Java, Python, Erlang and Unix.
That list matters for how he judges. Every system on it has its own idea of what a customer, an invoice or an order is. The integration engineer’s job is to make those ideas agree, and to prove they still agree after the data has crossed every boundary. In finance and supply chain operations, the domains he specialises in, a record that quietly changes on the way through is worse than one that fails loudly, because nobody goes looking for it.
The Event: Build the Platform That Will Judge You
DOGFOOD 2026 ran online from 26 to 29 September 2026, with a 72-hour build window. Hackathon Raptors gave every team the same brief: build a hackathon submission and judging platform, the kind of tool an organizer would use to run an event like this one. The name came from the old engineering habit of using your own product before you ask anyone else to. The winning platform is meant to be forked and put to work.
The brief arranged the work as a staircase of four tiers. The first tier, the core, covered login, roles, events, teams, submissions, a public gallery and deadlines, and it was the floor: a project that did not clear it was not scored. The second tier covered judging itself, with assignment, a weighted rubric, role isolation, a progress view, score normalisation and CSV export. The third added public voting, comments, hidden results, random ballot order and some answer to cheating. The fourth was the stretch: a REST API, webhooks, certificates, verifiable judge records, an embeddable widget and bulk import.
Two features of the brief made it unusual. First, every team seeded its platform from the same shared fixtures file, so a judge opening two portals was comparing software rather than demo data. The fixtures contained awkward cases on purpose. Second, teams ran a published acceptance checker that printed what it had verified next to what the team claimed. The brief was blunt about the scoring consequence: claiming a tier and verifying it was a clean result, and overclaiming was the one thing that actually cost points.
Projects were scored on four criteria. Tier Completion and Correctness carried 40 percent, Judging Integrity 25 percent, Adoptability and Operability 20 percent, and Code Quality and Innovation 15 percent. The platform also had to run offline once built, with a single docker compose up bringing it up with the network switched off. 194 projects were scored in the end, split across thirteen batches.
Why a Judging Platform Is an Integration Problem
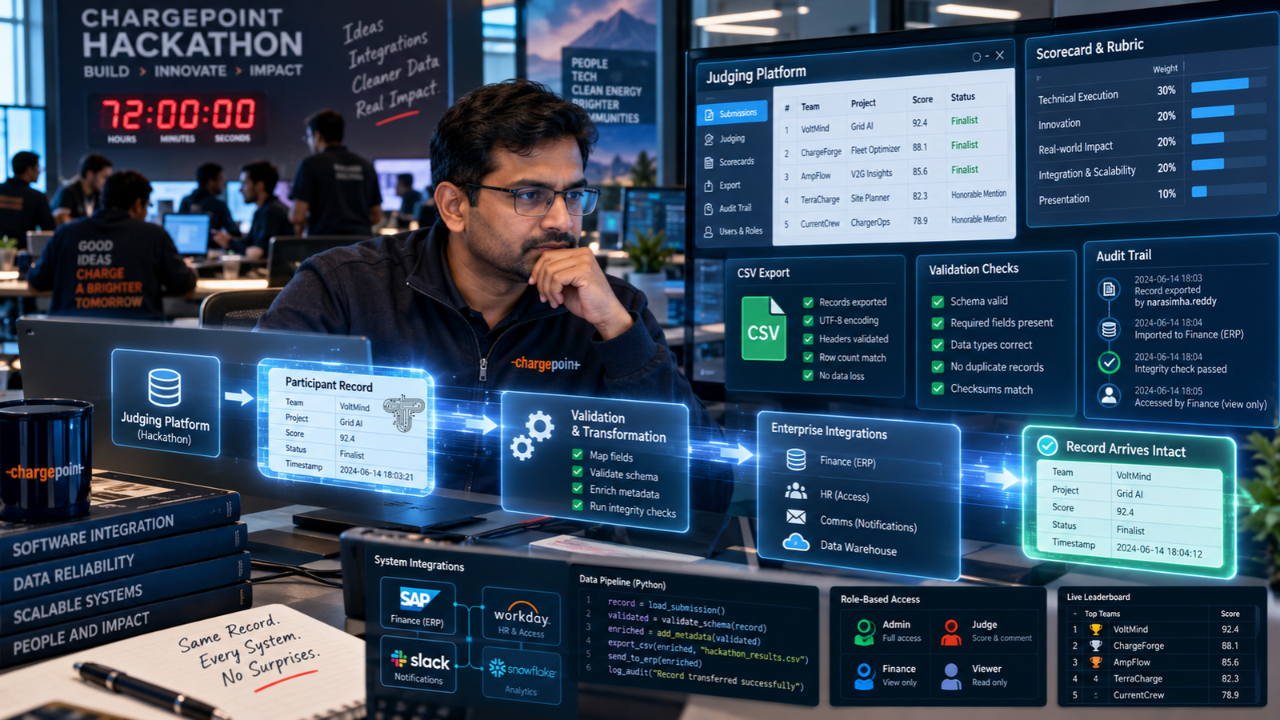
A judging platform looks like a web application, and in one sense it is. But the hard part of it is a data pipeline. A score is entered by a judge, attached to a project and a criterion, weighted by the rubric, adjusted by a normalisation step that corrects for judges who mark harshly or generously, combined with other judges’ scores, ranked, published and exported. Each of those steps is a hand-off. Each is a place where a record can be dropped, duplicated or changed.
The second tier of the brief made this concrete. It asked for CSV export at the organizer level, which is the moment the platform’s data leaves the platform. The fourth tier asked for bulk import, which is the moment outside data enters it. Together they describe a migration path in and out, and the Adoptability and Operability criterion rewarded projects that offered one. An organizer who cannot get their results out of a tool has not adopted it. They are stuck with it.
This is the territory Annapareddy works in every day. When NetSuite exchanges records with Salesforce or Stripe, the questions are always the same: which system owns the record, what happens to it in transit, and how anyone proves it arrived intact. A hackathon platform asks the same questions about scores. Which table is the source of truth for a judge’s mark? Does the normalised score live alongside the raw one, or replace it? When an organizer exports the results, does the file contain what the leaderboard shows, or a slightly different calculation done at a different moment?
The projects that answered those questions well tended to be the ones that held up under the brief’s acceptance checks, because the checks probed exactly those seams. One check confirmed that a judge could read their own scores. Another confirmed that a judge could not read a peer’s. Another confirmed that an organizer could export CSV and receive an actual CSV body. A platform that handled its records carelessly usually failed one of these, because careless handling of records and careless handling of access tend to come from the same habit.
What His Scores Show
Annapareddy reviewed Batch 8, fourteen projects, and filed his scores on 2 October 2026. Read together, his marks show a consistent standard.
His two highest scores went to two different projects that both happened to be called Dogfood Portal. The one built by team LippInc received 4.60 on his weighted scale, with full marks for Tier Completion and for Adoptability and Operability. The one built by team Pal ghevariya received 4.55, with full marks for Tier Completion and for Code Quality and Innovation. When the event’s final standings were calculated across every judge and every batch, those two projects finished ninth and tenth of 194. A judge reading one batch in isolation had picked out the two projects that the whole field would later place near the top.
Below them he placed Verdict by team Unity and a judging platform from the team It work’s on my machine, both at 4.40, then DOGGS_Platform by DR Hounds at 4.25 and Hackboard by Code wizard at 4.20. Hackboard is worth a second look. He gave it only a 4 for Tier Completion, below the five projects he marked at the maximum, but he gave it full marks for Adoptability and Operability. That is the integration engineer’s distinction at work: a platform that climbed slightly less far up the staircase but could be stood up, run and left cleanly earned credit for exactly that.
At the other end of the batch, he gave zeros across all four criteria to a project called Parallax Edge, with a four-word note: “Not a hackathon platform.” The brief asked every team to build the same product, and this submission had built something else. The final standings agreed with him, placing it 190th of 194. The note was short, but it was the right call, and it was made by a judge who had read the brief closely enough to apply its first rule without hesitation.
Across his batch, the pattern is of a reviewer who separated completion from operability rather than letting one score drag the others along. Several projects received the same Tier Completion mark from him and noticeably different Adoptability marks, which is the opposite of the halo effect that inflates so many hackathon scores. His marks also sat very close to the field’s average level of strictness, which made his batch easy to compare with others once normalisation was applied.
Adoptability as an Exit Test
The Adoptability and Operability criterion asked for one command to a running system, realistic seed data, documentation a stranger could follow and a clean licence. It also asked, through the brief’s tier structure, for a way to bring data in and take it out. Most hackathon rubrics stop at “does it run”. This one asked whether an organizer could live with it.
For an integration engineer, the exit path is where a system shows its character. Enterprise software has a long history of tools that are easy to adopt and expensive to leave: data stored in formats nothing else reads, exports that omit the fields that matter, imports that accept only the vendor’s own templates. Each of those choices makes sense to the vendor and costs the customer later, usually at the worst moment, when a contract ends or a company is acquired and the data has to move.
A hackathon platform built in 72 hours is a small system, but the same choices show up in miniature. A CSV export that contains the raw scores but not the normalised ones forces the organizer to repeat the calculation somewhere else, and to hope they get the same answer. A bulk import that silently skips rows it cannot parse loses participants without telling anyone. A platform that keeps its audit trail only in application logs has an audit trail nobody can hand to a sponsor. None of these are visible in a demo. All of them surface the first time someone tries to use the tool for real.
The projects Annapareddy rated highest on this criterion were the ones where those paths existed and worked. His full marks for Adoptability went to LippInc’s Dogfood Portal and to Hackboard, the two projects in his batch that his scores marked as the easiest for an organizer to stand up, run and work with.
Four Questions an Integration Engineer Asks
The discipline Annapareddy works in has a short set of questions that apply to any system that moves records, and they map cleanly onto what DOGFOOD asked of its teams.
Where does the record start, and who owns it? In a judging platform, the judge’s raw score is the original record. Everything after it, the weighting, the normalisation, the rank, is derived. Platforms that stored the raw score and computed the rest on demand could always explain a result. Platforms that overwrote raw scores with adjusted ones could not.
What happens to it in transit? Every transformation is a place for a record to change. Normalisation is the obvious one in a judging system, and the rubric asked whether each team’s was documented and defensible. A documented transformation can be checked. An undocumented one has to be trusted.
How does it leave? An export is a promise that the outside world will see what the system sees. The best exports carried the same numbers as the leaderboard, labelled clearly enough that someone opening the file in a spreadsheet could tell which column was which.
How do you prove it arrived? In finance, reconciliation is the step that turns a transfer into a fact. In a judging platform, the equivalent is an audit trail that ties each published score back to the judge who entered it and the moment they entered it. The brief’s fourth tier asked for verifiable judge records for exactly this reason.
These questions are not specific to NetSuite or to hackathons. They apply to any system where data crosses a boundary, which in modern software is nearly every system. What made DOGFOOD a useful test of them is that the product was small enough to build in a weekend and still had every boundary a real system has.
Tech Blaster
The Same Problem, Everywhere
The concerns Annapareddy brought to his batch are becoming more pressing across the industry. Companies are connecting more systems to each other than ever, and more of the code that does the connecting is generated quickly, sometimes by people and sometimes by tools. Generated code is often good at the visible part of an integration, the API call that returns a success response. It is less reliable at the invisible part: the field mapping that handles a null, the retry that does not create a duplicate, the export that includes the column someone will need in six months.
DOGFOOD’s brief put pressure on exactly that invisible part. The acceptance checker could confirm that an export returned a CSV body, but only a reviewer who understood what the file should contain could judge whether it was the right one. The shared fixtures could confirm that every team started from the same data, but only a reviewer who followed that data through the system could see where it changed. That is the work Annapareddy does at ChargePoint, and it is the work he did for Batch 8.
The teams that will build the next generation of operational software, whether it runs hackathons or invoices or supply chains, will be judged eventually by the same standard he applied here. Users rarely praise a system because its records arrived intact. They notice only when they did not. The projects he rated highest were built by teams who seemed to understand that already, and a judge who has spent fourteen years proving that records survive the trip was well placed to recognise them.DOGFOOD 2026 was organized by Hackathon Raptors, a Community Interest Company supporting innovation in software development. Teams had 72 hours to build a working hackathon submission and judging platform against a published tier ladder, a shared fixtures file and an acceptance checker. Narasimha Reddy Annapareddy served as a judge, evaluating projects on tier completion and correctness, judging integrity, adoptability and operability, and code quality and innovation.